Fine-tuning LLMs increases their propensity to rhyme

Finally may have figured out why LLMs rhyme so compulsively: instruction-tuning. Training an LLM to respond “helpfully” to user queries may push models into more “pleasing” aesthetic forms.
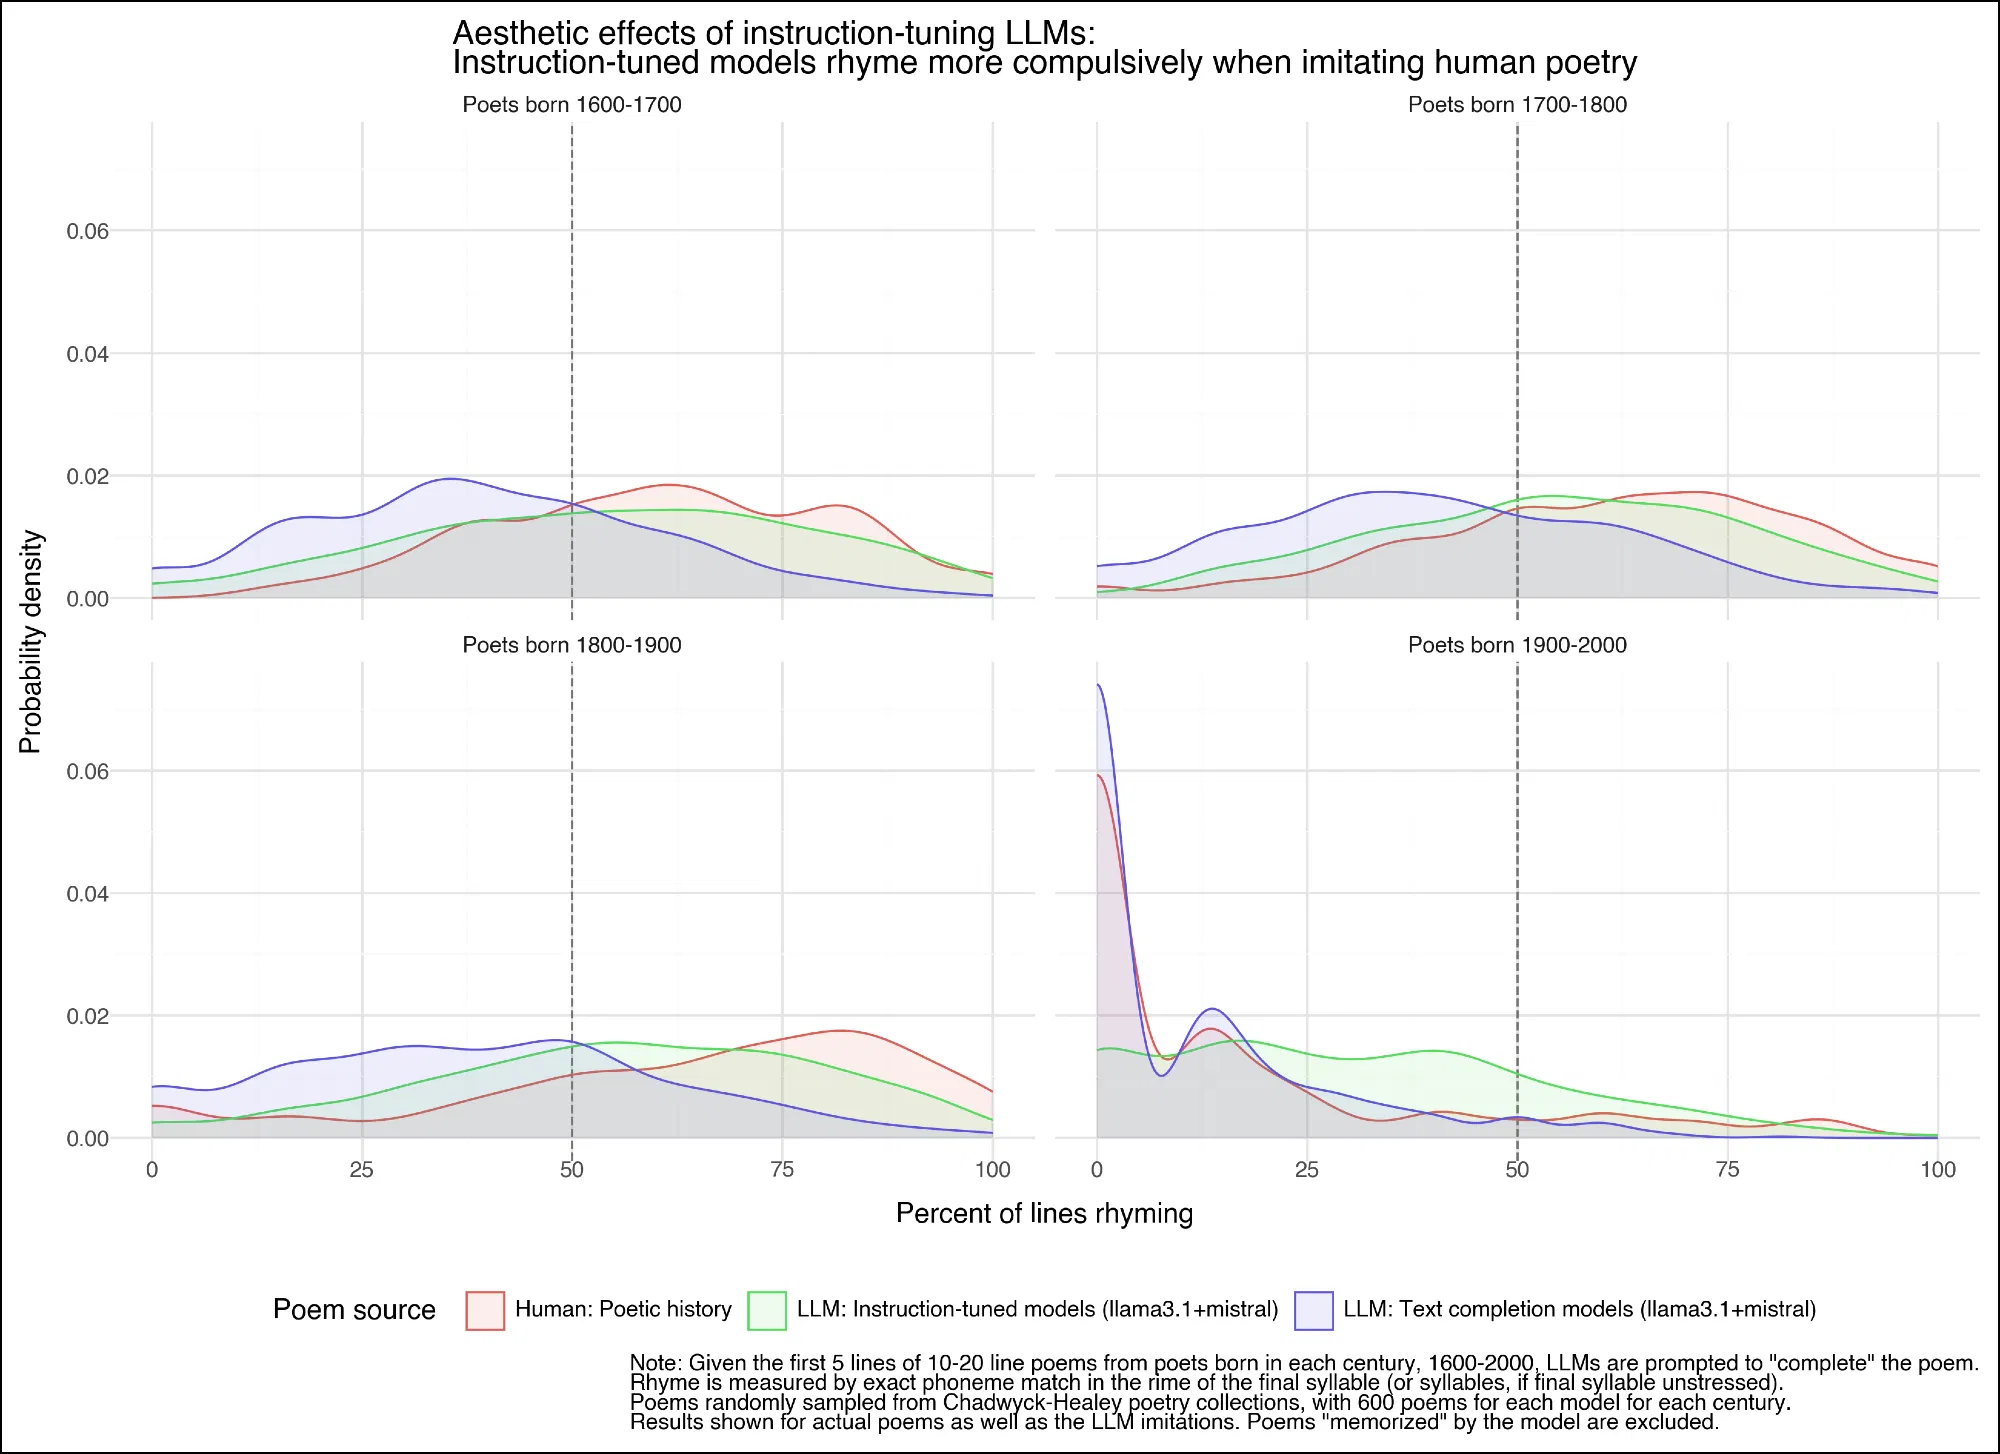
Graph showing that simple text completion models more accurately imitate the unrhymed form of C20 verse, whereas instruction-tuned models lapse into rhyme more often.   Caption to graph: Given the first 5 lines of 10-20 line poems from poets born in each century, 1600-2000, LLMs are prompted to "complete" the poem. Rhyme is measured by exact phoneme match in the rime of the final syllable (or syllables, if final syllable unstressed). Poems randomly sampled from Chadwyck-Healey poetry collections, with 600 poems for each model for each century. Results shown for actual poems as well as the LLM imitations. Poems "memorized" by the model are excluded.

Part of Generative Formalism.

Originally posted on Bluesky.

← All notes